Automated Web Scraping and AI-Driven Data Enrichment
Serverless
AWS Lambda execution with 15-min timeout
Hybrid
HTTP Requests & Playwright headless browser
AI-Driven
Automated lead qualification via Gemini LLM
What I built
- 01
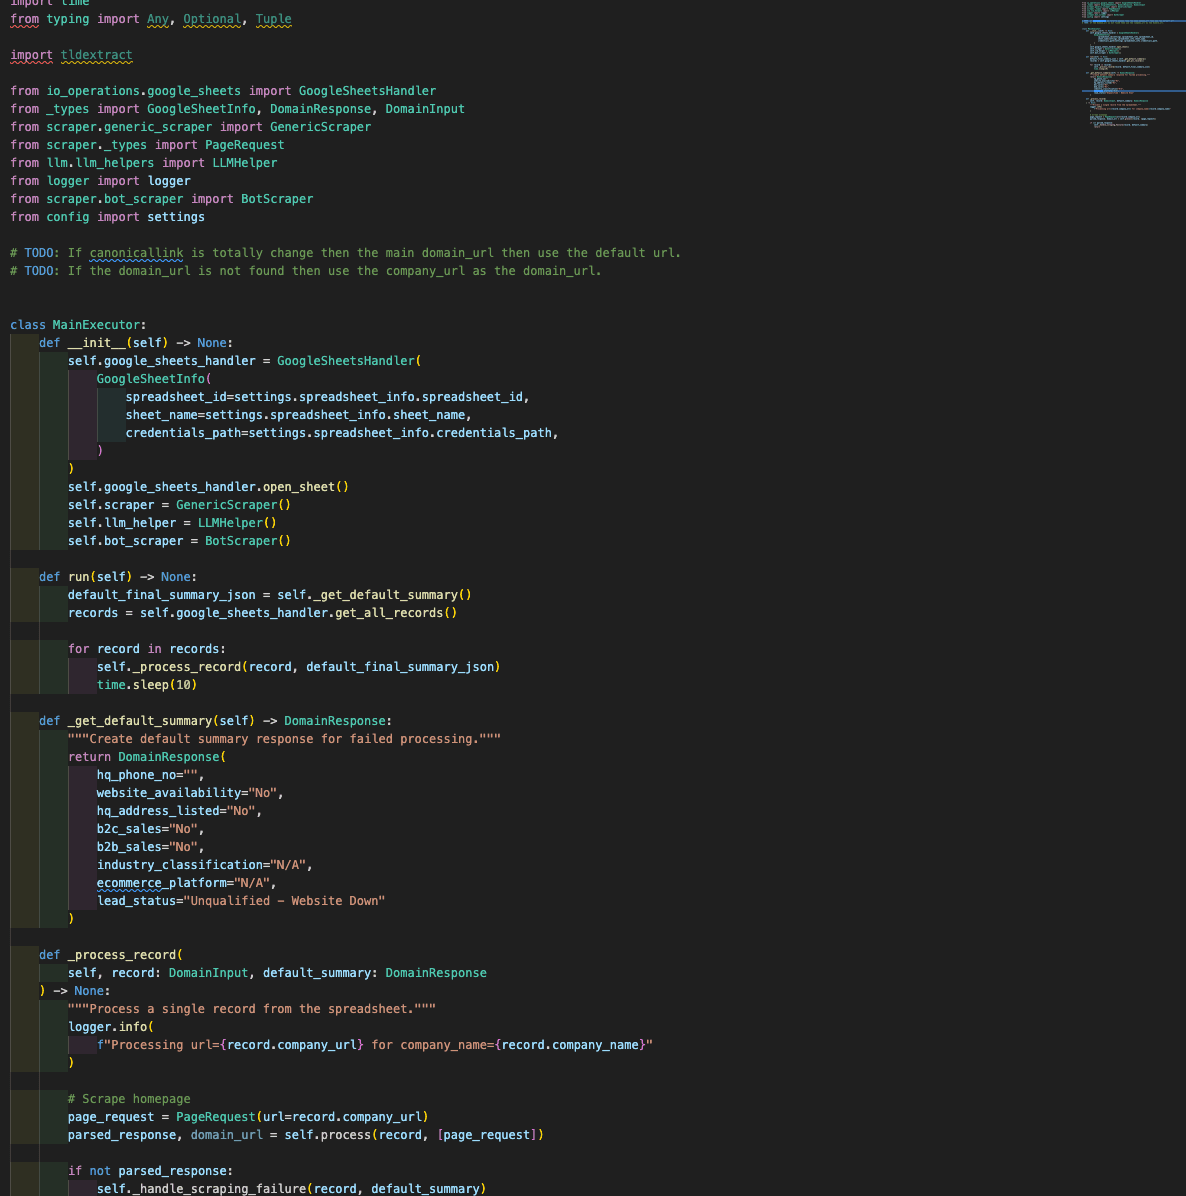
Engineered a dual-engine scraping framework consisting of a lightweight HTTP 'Generic Scraper' for fast static fetches and a headless Playwright 'Bot Scraper' to reliably render and extract data from complex, JavaScript-heavy target websites.
- 02
Integrated a specialized HTML parser module that sanitizes raw markup by stripping unnecessary tags, scripts, and layout clutter to optimize token usage and context relevance for downstream language model processing.
- 03
Built intelligent LLM orchestration modules using the Google Gemini API, designing focused prompts that transform unstructured website text into structured business intelligence, accurately identifying live domain status, physical addresses, B2B/B2C business models, verified industry classifications, and underlying e-commerce technologies.
- 04
Automated bidirectional Google Sheets synchronization (`io_operations`), reading target company names and domains dynamically and streaming back qualified analysis results straight into corresponding spreadsheet columns.
- 05
Packaged the entire application into a custom Docker image supporting custom environment configurations like `MAX_INPUT_RECORDS` and deployed it seamlessly to AWS Lambda via Amazon ECR, architected to handle long-running, 15-minute serverless execution timeouts.
Stack
Want something like this built for your product?